Note
Go to the end to download the full example code.
Equilibrium aluminium structure factors: Schörner et al. (2022)
Note
HNC, VMHNC and MD use the recalculated IS-QOZ potentials. See Otter 0.4.1 numerical validation for verification and scope.
This benchmark compares Otter \(S_{ii}(k)\) with two curves digitized from Figure 2 of Schörner et al. [2022]. Each state is calculated with LDA-PW92 and PBE. For each XC model, ordinary HNC and Rosenfeld–Ashcroft VMHNC reuse exactly the same IS electronic state and QOZ pair potential. Classical LAMMPS MD uses the potential from that same electronic state. Both states have \(T_e=T_i\): 1 eV at \(\rho=4.712\) g cm-3 and 5 eV at \(\rho=8.1\) g cm-3.
The raw 1 eV ordinate is displaced downward because only the 5 eV curve was used to calibrate the digitization. The loader therefore applies the audited correction \(S_{ii}^{\mathrm{corrected}}=S_{ii}^{\mathrm{stored}}+1.5\) to the 1 eV curve only. The source CSV remains unchanged; the transformation is recorded in its manifest and tested explicitly.
VMHNC uses a variational hard-sphere bridge. It is not IEMHNC: the latter maps an OCP bridge to a Yukawa one-component plasma (YOCP). The PA-QOZ potential used here is not assumed to be Yukawa, so no IEMHNC label is attached without an additional, explicitly audited Yukawa mapping.
Reproduction
From the root of the complete Otter checkout, using Poetry, run:
poetry run python benchmarks/examples/plot_schorner_et_al_2022_al_sii.py
Downloads are optional: .ipynb launches this repository script; .zip
contains both formats. See Reproducing examples and benchmarks for setup.
The script calculates the states from their input parameters and then plots the results. No bundled Otter NPZ is required. Numerical outputs are written locally; literature reference tables remain inputs to the comparison.
Reproducing the MD curves also requires LAMMPS and MPI and can take hours. The LDA/PBE calculations require the optional Libxc bindings. AA calculations keep one continuum worker per atom.
Recorded results
The figures and output below are from the recorded validation run; running the source recalculates them with the installed Otter version.
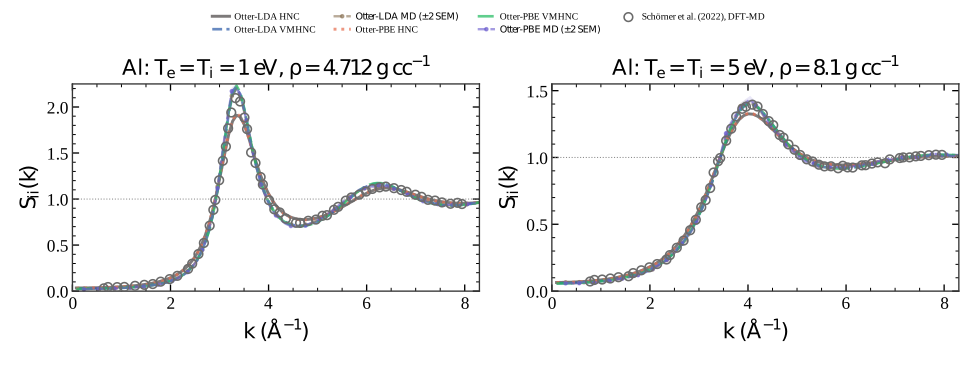
Recorded terminal output
case   method         RMSE          MAE   max|delta|
      al_rho4p712_te1_ti1_lda      HNC   4.9658e-02   3.0674e-02   2.0372e-01
      al_rho4p712_te1_ti1_lda    VMHNC   4.6000e-02   3.4601e-02   1.4634e-01
      al_rho4p712_te1_ti1_lda       MD   4.8143e-02   3.2460e-02   1.8295e-01
      al_rho4p712_te1_ti1_lda   HNC-MD   7.2546e-02
      al_rho4p712_te1_ti1_lda VMHNC-MD   1.4562e-02
      al_rho4p712_te1_ti1_pbe      HNC   4.5393e-02   2.7531e-02   1.8828e-01
      al_rho4p712_te1_ti1_pbe    VMHNC   5.2763e-02   3.9434e-02   1.6378e-01
      al_rho4p712_te1_ti1_pbe       MD   5.6943e-02   3.8731e-02   2.0250e-01
      al_rho4p712_te1_ti1_pbe   HNC-MD   7.6076e-02
      al_rho4p712_te1_ti1_pbe VMHNC-MD   1.5120e-02
        al_rho8p1_te5_ti5_lda      HNC   2.5319e-02   1.8657e-02   7.2412e-02
        al_rho8p1_te5_ti5_lda    VMHNC   1.0269e-02   7.6379e-03   3.8319e-02
        al_rho8p1_te5_ti5_lda       MD   1.4542e-02   1.1971e-02   3.4910e-02
        al_rho8p1_te5_ti5_lda   HNC-MD   2.9593e-02
        al_rho8p1_te5_ti5_lda VMHNC-MD   1.0556e-02
        al_rho8p1_te5_ti5_pbe      HNC   2.4161e-02   1.7863e-02   7.0513e-02
        al_rho8p1_te5_ti5_pbe    VMHNC   1.1200e-02   8.7485e-03   3.6988e-02
        al_rho8p1_te5_ti5_pbe       MD   1.8042e-02   1.3992e-02   5.6386e-02
        al_rho8p1_te5_ti5_pbe   HNC-MD   3.0630e-02
        al_rho8p1_te5_ti5_pbe VMHNC-MD   1.2234e-02
from __future__ import annotations
from concurrent.futures import ProcessPoolExecutor, as_completed
import hashlib
import json
import os
from pathlib import Path
import shutil
import subprocess
import time
from typing import Any
import matplotlib.pyplot as plt
import numpy as np
from scipy.constants import physical_constants
from otter.electronic.full_external import FullExternalConfig
from otter import (
__version__ as otter_version,
PlasmaWorkflowConfig,
continue_plasma_workflow_from_electronic_result,
solve_plasma_workflow,
)
from otter.literature import citation_keys_for_xc_model
from otter.numerics.constants import BOHR_TO_ANGSTROM, EV_TO_KELVIN, HA_TO_EV
from otter.plotting import (
MODEL_STYLES,
PALETTES,
grid_figsize,
save_figure,
set_style,
)
# =============================================================================
# User input
# =============================================================================
USE_PRECOMPUTED_DATA = False
if os.environ.get("OTTER_RECOMPUTE_SCHORNER_AL", "0") == "1":
USE_PRECOMPUTED_DATA = False
USE_RECOMPUTED_CANDIDATES = False
# Four independent state/XC cases; each AA uses the single-worker default.
# The optional MD protocol has its own MPI controls.
MAX_CASE_WORKERS = 1
HNC_CLOSURE_TOL = 2.5e-3
VMHNC_ETA_TOL = 1.0e-6
K_RETAIN_MAX_BOHR_INV = 20.0
R_RETAIN_MAX_BOHR = 20.0
RUN_SAME_POTENTIAL_MD = True
if os.environ.get("OTTER_RUN_SCHORNER_SAME_POTENTIAL_MD", "1") == "0":
RUN_SAME_POTENTIAL_MD = False
LAMMPS_EXECUTABLE = "lmp"
MPI_LAUNCHER = "mpirun"
MAX_PARALLEL_MD_CASES = 1
MPI_PROCESSES_PER_MD_CASE = 10
MD_CELLS_PER_AXIS = 8 # 4 * 8**3 = 2048 Al ions.
MD_TIMESTEP_OMEGA_P_INV = 5.0e-3
MD_MIN_TIMESTEP_FS = 0.01
MD_EQUILIBRATION_OMEGA_P_INV = 50.0
MD_PRODUCTION_OMEGA_P_INV = 500.0
MD_RDF_BINS = 500
MD_K_MAX_BOHR_INV = 4.5 # Covers the plotted 8.3 inverse-angstrom range.
MD_K_BIN_WIDTH_ANGSTROM_INV = 0.1
MD_RECIPROCAL_BATCH_SIZE = 512
# =============================================================================
BENCHMARK_ID = "schorner_et_al_2022_al_sii"
SCHEMA = "otter_schorner_2022_al_sii_v4"
REFERENCE_SII_OFFSET = {
"al_rho4p712_te1_ti1": 1.5,
"al_rho8p1_te5_ti5": 0.0,
}
XC_MODELS: tuple[dict[str, str], ...] = (
{"key": "lda", "xc_model": "lda_pw", "label": "Otter-LDA"},
{"key": "pbe", "xc_model": "pbe", "label": "Otter-PBE"},
)
STATES: tuple[dict[str, Any], ...] = (
{
"state_id": "al_rho4p712_te1_ti1",
"rho_g_cc": 4.712,
"te_ev": 1.0,
"ti_ev": 1.0,
},
{
"state_id": "al_rho8p1_te5_ti5",
"rho_g_cc": 8.1,
"te_ev": 5.0,
"ti_ev": 5.0,
},
)
def case_id(state: dict[str, Any], xc: dict[str, str]) -> str:
"""Return the stable identifier for one thermodynamic state/XC pair."""
return f"{state['state_id']}_{xc['key']}"
def repository_root() -> Path:
"""Locate source and reference inputs, independently of numerical outputs."""
candidates = [Path.cwd().resolve(), *Path.cwd().resolve().parents]
source_file = globals().get("__file__")
if source_file is not None:
candidates.extend(Path(source_file).resolve().parents)
for candidate in candidates:
if (candidate / "pyproject.toml").is_file() and (candidate / "src/otter").is_dir():
return candidate
raise FileNotFoundError("Run from an Otter source checkout with its dependencies installed.")
ROOT = repository_root()
SCRIPT_PATH = ROOT / "benchmarks/examples/plot_schorner_et_al_2022_al_sii.py"
REFERENCE_DIR = ROOT / "benchmarks" / "reference_data" / BENCHMARK_ID
BASELINE_DIR = ROOT / "benchmarks" / "baselines" / BENCHMARK_ID
OUTPUT_DIR = ROOT / "benchmarks" / "outputs" / BENCHMARK_ID
CANDIDATE_DIR = OUTPUT_DIR / "gallery_recomputed"
FIGURE_DIR = OUTPUT_DIR / "figures"
def sha256_file(path: Path) -> str:
"""Return a streaming SHA-256 digest."""
digest = hashlib.sha256()
with path.open("rb") as stream:
for block in iter(lambda: stream.read(1024 * 1024), b""):
digest.update(block)
return digest.hexdigest()
def load_reference_curves() -> dict[str, tuple[np.ndarray, np.ndarray]]:
"""Load the raw CSV and apply only the manifest-declared y corrections."""
manifest = json.loads(
(REFERENCE_DIR / "manifest.json").read_text(encoding="utf-8")
)
if manifest.get("reference_id") != BENCHMARK_ID:
raise ValueError("Unexpected Schörner reference manifest.")
file_record = manifest["files"][0]
path = REFERENCE_DIR / str(file_record["path"])
if sha256_file(path) != str(file_record["sha256"]):
raise RuntimeError(f"Checksum mismatch for {path}.")
values = np.genfromtxt(path, delimiter=",", skip_header=2)
finite_four_columns = (
values.ndim == 2
and values.shape[1] == 4
and np.all(np.isfinite(values))
)
if not finite_four_columns:
raise ValueError("Expected four finite numeric reference columns.")
curves: dict[str, tuple[np.ndarray, np.ndarray]] = {}
for state in manifest["states"]:
state_id = str(state["state_id"])
correction = float(state["sii_additive_correction"])
if correction != REFERENCE_SII_OFFSET[state_id]:
raise ValueError(f"Unexpected ordinate correction for {state_id}.")
k = np.asarray(values[:, int(state["k_column"])], dtype=float)
sii = (
np.asarray(values[:, int(state["sii_column"])], dtype=float)
+ correction
)
if np.any(np.diff(k) <= 0.0) or np.any(sii < 0.0):
raise ValueError(f"Invalid corrected reference curve for {state_id}.")
curves[state_id] = (k, sii)
if set(curves) != {str(state["state_id"]) for state in STATES}:
raise ValueError("Reference state coverage is incomplete.")
return curves
def load_npz(path: Path) -> dict[str, np.ndarray]:
"""Load one portable, pickle-free Otter archive."""
with np.load(path, allow_pickle=False) as archive:
result = {key: np.asarray(archive[key]) for key in archive.files}
if any(value.dtype.hasobject for value in result.values()):
raise TypeError(f"Object arrays are forbidden in {path}.")
return result
def load_precomputed_states() -> dict[str, dict[str, np.ndarray]]:
"""Verify and load the four accepted Otter state/XC baselines."""
manifest = json.loads(
(BASELINE_DIR / "manifest.json").read_text(encoding="utf-8")
)
if manifest.get("benchmark_id") != BENCHMARK_ID:
raise ValueError("Unexpected Schörner benchmark manifest.")
loaded: dict[str, dict[str, np.ndarray]] = {}
for record in manifest["states"]:
if record.get("status") != "accepted":
raise RuntimeError(f"Unaccepted state: {record['state_id']}.")
path = BASELINE_DIR / str(record["baseline_file"])
if sha256_file(path) != str(record["baseline_sha256"]):
raise RuntimeError(f"Checksum mismatch for {path}.")
payload = load_npz(path)
state_id = str(payload["state_id"].item())
if state_id != str(record["state_id"]):
raise ValueError(f"State identifier mismatch in {path}.")
if str(payload["schema_version"].item()) != SCHEMA:
raise ValueError(f"Obsolete Schörner baseline schema in {path}.")
required = {
"sii_k",
"vmhnc_sii_k",
"vmhnc_eta",
"md_sii_k",
"md_sii_block_sem",
"md_nve_relative_energy_drift",
}
if not required <= set(payload):
raise ValueError(f"Incomplete closure/MD baseline in {path}.")
loaded[state_id] = payload
expected = {case_id(state, xc) for state in STATES for xc in XC_MODELS}
if set(loaded) != expected:
raise RuntimeError("Accepted baseline state coverage is incomplete.")
return loaded
def load_recomputed_candidates() -> dict[str, dict[str, np.ndarray]]:
"""Load a complete candidate set without treating it as accepted data."""
manifest = json.loads(
(CANDIDATE_DIR / "candidate_manifest.json").read_text(encoding="utf-8")
)
if manifest.get("benchmark_id") != BENCHMARK_ID:
raise ValueError("Unexpected Schörner candidate manifest.")
records = {str(record["state_id"]): record for record in manifest["states"]}
expected = {case_id(state, xc) for state in STATES for xc in XC_MODELS}
if set(records) != expected:
raise RuntimeError("Candidate manifest does not cover all state/XC cases.")
loaded: dict[str, dict[str, np.ndarray]] = {}
for identifier, record in records.items():
if record.get("status") != "candidate_unreviewed":
raise RuntimeError(f"Candidate {identifier} is not reviewable.")
path = CANDIDATE_DIR / str(record["baseline_file"])
if sha256_file(path) != str(record["baseline_sha256"]):
raise RuntimeError(f"Candidate checksum mismatch for {path}.")
loaded[identifier] = load_npz(path)
return loaded
def workflow_config(
state: dict[str, Any],
xc: dict[str, str],
*,
bridge_model: str = "none",
) -> PlasmaWorkflowConfig:
"""Build one equilibrium IS workflow; only the closure may change."""
return PlasmaWorkflowConfig(
elements=["Al"],
temperature_ev=float(state["te_ev"]),
ion_temperature_ev=float(state["ti_ev"]),
rho_g_cc=float(state["rho_g_cc"]),
xc_model=str(xc["xc_model"]),
hnc_closure_transform_tol=float(HNC_CLOSURE_TOL),
hnc_bridge_model=str(bridge_model),
**({"vmhnc_eta_tol": float(VMHNC_ETA_TOL)} if bridge_model != "none" else {}),
show_progress=False,
)
def _pack_structure_result(workflow: dict[str, Any]) -> dict[str, np.ndarray]:
"""Validate and retain one electronic/QOZ closure result."""
electronic = dict(workflow["electronic"]["result"])
ion = dict(workflow["ion"])
if electronic.get("stage2_converged") is not True:
raise RuntimeError("Full average-atom stage 2 did not converge.")
if dict(electronic.get("ext_status", {})).get("converged") is not True:
raise RuntimeError("External fixed-mu average atom did not converge.")
if str(electronic.get("threshold_state_status", "")).lower() == "unresolved":
raise RuntimeError("The threshold-state representation is unresolved.")
if ion.get("hnc_converged") is not True:
raise RuntimeError("The ionic closure did not reach a physical point.")
if float(ion["hnc_output_residual"]) > float(
workflow["configuration"]["hnc_tol"]
):
raise RuntimeError("Ionic closure residual exceeds its tolerance.")
if float(ion["closure_transform_max_abs"]) > HNC_CLOSURE_TOL:
raise RuntimeError("The g/S transform-closure audit failed.")
r = np.asarray(ion["r"], dtype=float)
k = np.asarray(ion["k"], dtype=float)
r_mask = r <= R_RETAIN_MAX_BOHR
k_mask = k <= K_RETAIN_MAX_BOHR_INV
return {
"r_bohr": r[r_mask],
"gii_r": np.asarray(ion["gij_r"][0, 0], dtype=float)[r_mask],
"vii_r_ha": np.asarray(ion["vii_r"], dtype=float)[r_mask],
"k_bohr_inv": k[k_mask],
"sii_k": np.asarray(ion["sij_k"][0, 0], dtype=float)[k_mask],
"ion_density_bohr3": np.asarray(np.asarray(ion["n_i"]).item()),
"mu_ha": np.asarray(float(electronic["mu"])),
"r_ws_bohr": np.asarray(float(electronic["r_ws"])),
"zbar_partition": np.asarray(np.asarray(ion["zbar_partition"]).item()),
"threshold_state_status": np.asarray(
str(electronic.get("threshold_state_status", "none"))
),
"hnc_solver_path": np.asarray(str(ion["hnc_solver_path"])),
"hnc_output_residual": np.asarray(float(ion["hnc_output_residual"])),
"closure_transform_max_abs": np.asarray(
float(ion["closure_transform_max_abs"])
),
"hnc_bridge_model": np.asarray(str(ion["hnc_bridge_model"])),
}
def pack_result(
hnc_workflow: dict[str, Any],
vmhnc_workflow: dict[str, Any],
state: dict[str, Any],
xc: dict[str, str],
hnc_elapsed_s: float,
vmhnc_elapsed_s: float,
) -> dict[str, np.ndarray]:
"""Store HNC and VMHNC from one shared IS electronic/QOZ potential."""
hnc = _pack_structure_result(hnc_workflow)
vmhnc = _pack_structure_result(vmhnc_workflow)
electronic = dict(hnc_workflow["electronic"]["result"])
vmhnc_ion = dict(vmhnc_workflow["ion"])
xc_model = str(xc["xc_model"])
xc_provenance = dict(electronic["xc_provenance"])
if str(xc_provenance.get("model")) != xc_model:
raise RuntimeError("The electronic result reports the wrong XC model.")
if str(hnc["hnc_bridge_model"].item()) != "none":
raise RuntimeError("The ordinary-HNC curve unexpectedly used a bridge.")
if str(vmhnc["hnc_bridge_model"].item()) != "rosenfeld_ashcroft":
raise RuntimeError("The VMHNC curve did not use Rosenfeld--Ashcroft.")
if not np.isclose(
float(hnc["mu_ha"]), float(vmhnc["mu_ha"]), rtol=0.0, atol=1e-12
):
raise RuntimeError("HNC and VMHNC did not reuse the electronic state.")
if not np.allclose(
hnc["vii_r_ha"], vmhnc["vii_r_ha"], rtol=0.0, atol=0.0
):
raise RuntimeError("HNC and VMHNC did not reuse the QOZ pair potential.")
payload: dict[str, np.ndarray] = {
"schema_version": np.asarray(SCHEMA),
"storage_profile": np.asarray("benchmark_analysis"),
"state_id": np.asarray(case_id(state, xc)),
"thermodynamic_state_id": np.asarray(str(state["state_id"])),
"element": np.asarray("Al"),
"rho_g_cc": np.asarray(float(state["rho_g_cc"])),
"te_ev": np.asarray(float(state["te_ev"])),
"ti_ev": np.asarray(float(state["ti_ev"])),
"structure_model": np.asarray("IS"),
"xc_model": np.asarray(xc_model),
"xc_label": np.asarray(str(xc["label"])),
"xc_provenance_json": np.asarray(
json.dumps(xc_provenance, sort_keys=True, separators=(",", ":"))
),
"producer_elapsed_s": np.asarray(hnc_elapsed_s + vmhnc_elapsed_s),
"hnc_elapsed_s": np.asarray(hnc_elapsed_s),
"vmhnc_elapsed_s": np.asarray(vmhnc_elapsed_s),
**hnc,
**{
f"vmhnc_{key}": value
for key, value in vmhnc.items()
if key
in {
"sii_k",
"hnc_solver_path",
"hnc_output_residual",
"closure_transform_max_abs",
"hnc_bridge_model",
}
},
"vmhnc_eta": np.asarray(float(vmhnc_ion["vmhnc_eta"])),
"vmhnc_sigma_bohr": np.asarray(float(vmhnc_ion["vmhnc_sigma_bohr"])),
"vmhnc_variational_residual": np.asarray(
float(vmhnc_ion["vmhnc_variational_residual"])
),
}
metadata = {
"schema_version": "otter_compact_archive_metadata_v1",
"archive_role": "project_generated_example_or_benchmark_baseline",
"archive_schema_version": SCHEMA,
"package_id": BENCHMARK_ID,
"configuration": {
"elements": ["Al"],
"structure_model": "IS",
"temperature_ev": float(state["te_ev"]),
"ion_temperature_ev": float(state["ti_ev"]),
"rho_g_cc": float(state["rho_g_cc"]),
"xc_model": xc_model,
"ionic_closures": ["HNC", "Rosenfeld--Ashcroft VMHNC"],
"electronic_state_reused_between_closures": True,
"continuum_workers_per_case": FullExternalConfig.cont_n_jobs,
"hnc_tolerance": float(workflow_config(state, xc).hnc_tol),
"hnc_transform_closure_tolerance": HNC_CLOSURE_TOL,
"vmhnc_eta_tolerance": VMHNC_ETA_TOL,
},
"state": {
"state_id": case_id(state, xc),
"thermodynamic_state_id": str(state["state_id"]),
"element": "Al",
"rho_g_cc": float(state["rho_g_cc"]),
"te_ev": float(state["te_ev"]),
"ti_ev": float(state["ti_ev"]),
"xc_model": xc_model,
"xc_label": str(xc["label"]),
},
"producer": {
"project": "Otter",
"version": otter_version,
"script_relative_path": str(SCRIPT_PATH.relative_to(ROOT)),
"script_sha256": sha256_file(SCRIPT_PATH),
},
"citation_keys": [
"SchornerEtAl2022",
"RosenfeldAshcroft1979",
"Faussurier2004",
"ThompsonEtAl2022",
*citation_keys_for_xc_model(xc_model),
],
"convergence": {
"aa_stage2_converged": True,
"aa_ext_converged": True,
"threshold_state_status": str(hnc["threshold_state_status"].item()),
"hnc_output_residual": float(hnc["hnc_output_residual"]),
"hnc_closure_transform_max_abs": float(
hnc["closure_transform_max_abs"]
),
"vmhnc_output_residual": float(vmhnc["hnc_output_residual"]),
"vmhnc_closure_transform_max_abs": float(
vmhnc["closure_transform_max_abs"]
),
"vmhnc_variational_residual": float(
vmhnc_ion["vmhnc_variational_residual"]
),
},
"fields": sorted(payload),
}
payload["metadata_json"] = np.asarray(
json.dumps(metadata, sort_keys=True, separators=(",", ":"))
)
return payload
def _write_lammps_pair_table(
path: Path,
r_bohr: np.ndarray,
potential_ha: np.ndarray,
) -> tuple[int, float]:
"""Write a shifted-force Al pair table in LAMMPS metal units."""
selected = (r_bohr >= 0.1) & (r_bohr <= R_RETAIN_MAX_BOHR)
radius = np.asarray(r_bohr[selected], dtype=float) * BOHR_TO_ANGSTROM
energy = np.asarray(potential_ha[selected], dtype=float) * HA_TO_EV
force = -np.gradient(energy, radius, edge_order=2)
force_cutoff = force[-1]
energy = energy - energy[-1] + (radius - radius[-1]) * force_cutoff
force = force - force_cutoff
with path.open("w", encoding="utf-8") as stream:
stream.write("# Otter IS-QOZ Al-Al pair potential\n\nAL_AL\n")
stream.write(f"N {radius.size}\n\n")
for index, (r_value, v_value, f_value) in enumerate(
zip(radius, energy, force), start=1
):
stream.write(
f"{index} {r_value:.12e} {v_value:.12e} {f_value:.12e}\n"
)
# Stay just inside the last text-serialized table point. Passing the
# rounded endpoint itself can be one ulp outside LAMMPS's parsed range.
return int(radius.size), float(radius[-1] - 1.0e-9)
def _read_lammps_rdf(path: Path) -> tuple[np.ndarray, np.ndarray]:
"""Return the RDF radius and all statistically independent blocks."""
rows = [
line.split()
for line in path.read_text(encoding="utf-8").splitlines()
if line.strip() and not line.startswith("#")
]
blocks: list[np.ndarray] = []
cursor = 0
while cursor < len(rows):
block_size = int(rows[cursor][1])
blocks.append(
np.asarray(rows[cursor + 1 : cursor + 1 + block_size], dtype=float)
)
cursor += block_size + 1
if len(blocks) < 2:
raise RuntimeError("LAMMPS produced fewer than two RDF blocks.")
values = np.stack(blocks)
return values[0, :, 1] / BOHR_TO_ANGSTROM, values[:, :, 2]
def _read_lammps_trajectory(path: Path) -> tuple[np.ndarray, float]:
"""Load wrapped Al coordinates and the cubic box length in Bohr."""
lines = path.read_text(encoding="utf-8").splitlines()
frames: list[np.ndarray] = []
box_length_angstrom: float | None = None
cursor = 0
while cursor < len(lines):
if lines[cursor] != "ITEM: TIMESTEP":
raise RuntimeError("Unexpected LAMMPS trajectory block.")
cursor += 2
if lines[cursor] != "ITEM: NUMBER OF ATOMS":
raise RuntimeError("Missing trajectory atom count.")
atoms = int(lines[cursor + 1])
cursor += 2
if not lines[cursor].startswith("ITEM: BOX BOUNDS"):
raise RuntimeError("Missing trajectory box bounds.")
bounds = np.asarray(
[[float(value) for value in lines[cursor + offset].split()[:2]]
for offset in (1, 2, 3)]
)
lengths = bounds[:, 1] - bounds[:, 0]
if not np.allclose(lengths, lengths[0], rtol=0.0, atol=1.0e-10):
raise RuntimeError("Direct S(k) requires a cubic MD cell.")
if box_length_angstrom is None:
box_length_angstrom = float(lengths[0])
cursor += 4
if lines[cursor] != "ITEM: ATOMS id x y z":
raise RuntimeError("Unexpected trajectory atom columns.")
values = np.asarray(
[[float(value) for value in line.split()]
for line in lines[cursor + 1 : cursor + 1 + atoms]],
dtype=float,
)
frames.append(values[np.argsort(values[:, 0]), 1:4])
cursor += atoms + 1
if len(frames) < 2 or box_length_angstrom is None:
raise RuntimeError("LAMMPS produced fewer than two trajectory frames.")
return np.stack(frames) / BOHR_TO_ANGSTROM, (
box_length_angstrom / BOHR_TO_ANGSTROM
)
def _direct_structure_factor(
positions_bohr: np.ndarray,
box_length_bohr: float,
k_max_bohr_inv: float,
) -> tuple[np.ndarray, np.ndarray, np.ndarray, np.ndarray]:
r"""Average every periodic density mode over radial bins and frames.
The complete half-space of reciprocal vectors is retained because
:math:`|\rho(-k)|^2=|\rho(k)|^2`. Processing vectors in batches bounds
memory without introducing the shell-sampling noise caused by randomly
capping the number of directions in each radial bin.
"""
fundamental = 2.0 * np.pi / box_length_bohr
n_max = int(np.floor(k_max_bohr_inv / fundamental))
integers = np.arange(-n_max, n_max + 1, dtype=int)
nx, ny, nz = np.meshgrid(integers, integers, integers, indexing="ij")
triplets = np.column_stack((nx.ravel(), ny.ravel(), nz.ravel()))
half_space = (
(triplets[:, 0] > 0)
| ((triplets[:, 0] == 0) & (triplets[:, 1] > 0))
| (
(triplets[:, 0] == 0)
& (triplets[:, 1] == 0)
& (triplets[:, 2] > 0)
)
)
triplets = triplets[half_space]
magnitudes = fundamental * np.sqrt(np.sum(triplets**2, axis=1))
within_cutoff = magnitudes <= k_max_bohr_inv
triplets = triplets[within_cutoff]
magnitudes = magnitudes[within_cutoff]
bin_width = MD_K_BIN_WIDTH_ANGSTROM_INV * BOHR_TO_ANGSTROM
radial_bin = np.floor(magnitudes / bin_width).astype(int)
populated_bins = np.unique(radial_bin)
vector_bin = np.searchsorted(populated_bins, radial_bin)
vectors_per_bin = np.bincount(vector_bin, minlength=populated_bins.size)
k_bin = (
np.bincount(vector_bin, weights=magnitudes) / vectors_per_bin
)
vectors = fundamental * triplets.astype(float)
frame_sii = np.empty((positions_bohr.shape[0], populated_bins.size))
for frame_index, positions in enumerate(positions_bohr):
mode_intensity = np.empty(vectors.shape[0])
for start in range(0, vectors.shape[0], MD_RECIPROCAL_BATCH_SIZE):
stop = min(start + MD_RECIPROCAL_BATCH_SIZE, vectors.shape[0])
phase = positions @ vectors[start:stop].T
amplitude = np.exp(1j * phase).sum(axis=0)
mode_intensity[start:stop] = (
np.abs(amplitude) ** 2 / positions.shape[0]
)
frame_sii[frame_index] = np.bincount(
vector_bin, weights=mode_intensity
) / vectors_per_bin
return (
k_bin,
np.mean(frame_sii, axis=0),
np.std(frame_sii, axis=0, ddof=1) / np.sqrt(frame_sii.shape[0]),
vectors_per_bin,
)
def _read_lammps_nve_audit(path: Path) -> tuple[float, float, str]:
"""Return relative NVE energy drift, mean temperature, and version."""
lines = path.read_text(encoding="utf-8").splitlines()
headers = [
index
for index, line in enumerate(lines)
if line.split()[:5] == ["Step", "Temp", "PotEng", "KinEng", "TotEng"]
]
if len(headers) < 2:
raise RuntimeError("LAMMPS log does not contain the NVE thermo block.")
rows: list[list[float]] = []
for line in lines[headers[-1] + 1 :]:
if line.startswith("Loop time"):
break
values = line.split()
if len(values) < 7:
continue
try:
rows.append([float(value) for value in values[:7]])
except ValueError:
continue
if len(rows) < 2:
raise RuntimeError("LAMMPS NVE thermo block is incomplete.")
drift = (rows[-1][4] - rows[0][4]) / abs(rows[0][4])
return float(drift), float(np.mean([row[1] for row in rows])), lines[0]
def run_same_potential_md(payload: dict[str, np.ndarray]) -> dict[str, np.ndarray]:
"""Run an audited NVT-to-NVE calculation with the stored QOZ potential."""
lammps = shutil.which(LAMMPS_EXECUTABLE)
launcher = shutil.which(MPI_LAUNCHER)
if lammps is None or launcher is None:
raise FileNotFoundError("LAMMPS and an MPI launcher are required for MD.")
identifier = str(payload["state_id"].item())
workdir = CANDIDATE_DIR / "md_work" / identifier
workdir.mkdir(parents=True, exist_ok=True)
table_points, cutoff_angstrom = _write_lammps_pair_table(
workdir / "al_al.table",
np.asarray(payload["r_bohr"], dtype=float),
np.asarray(payload["vii_r_ha"], dtype=float),
)
n_i = float(payload["ion_density_bohr3"])
zbar = float(payload["zbar_partition"])
mass_u = 26.9815385
mass_ratio = (
physical_constants["atomic mass constant"][0]
/ physical_constants["electron mass"][0]
)
atomic_time_ps = physical_constants["atomic unit of time"][0] * 1.0e12
omega_p_au = np.sqrt(4.0 * np.pi * n_i * zbar**2 / (mass_u * mass_ratio))
dt_omega = max(MD_TIMESTEP_OMEGA_P_INV,
MD_MIN_TIMESTEP_FS * 1e-3 / atomic_time_ps * omega_p_au)
timestep_ps = dt_omega / omega_p_au * atomic_time_ps
thermostat_damp_ps = 0.5 / omega_p_au * atomic_time_ps
equilibration_steps = round(
MD_EQUILIBRATION_OMEGA_P_INV / dt_omega
)
production_steps = round(
MD_PRODUCTION_OMEGA_P_INV / dt_omega
)
rdf_every, rdf_repeat = max(1, production_steps // 1000), 50
rdf_block_steps = rdf_every * rdf_repeat
lattice_angstrom = (4.0 / (n_i / BOHR_TO_ANGSTROM**3)) ** (1.0 / 3.0)
seed = 20260825 + sum((i + 1) * ord(char) for i, char in enumerate(identifier))
temperature_k = float(payload["ti_ev"]) * EV_TO_KELVIN
cells = MD_CELLS_PER_AXIS
thermostat_fix = (
f"fix thermostat all nvt temp {temperature_k:.8f} "
f"{temperature_k:.8f} {thermostat_damp_ps:.12e}"
)
rdf_fix = (
f"fix rdf all ave/time {rdf_every} {rdf_repeat} "
f"{rdf_block_steps} c_gr[*] mode vector ave one file rdf_blocks.dat"
)
input_text = f"""# Same-potential MD for {identifier}
units metal
dimension 3
boundary p p p
atom_style atomic
lattice fcc {lattice_angstrom:.12f}
region box block 0 {cells} 0 {cells} 0 {cells} units lattice
create_box 1 box
create_atoms 1 box
mass 1 {mass_u:.10f}
pair_style table linear {table_points}
pair_coeff 1 1 al_al.table AL_AL {cutoff_angstrom:.12f}
neighbor 2.0 bin
neigh_modify delay 0 every 1 check yes
velocity all create {temperature_k:.8f} {seed} mom yes rot no dist gaussian
timestep {timestep_ps:.12e}
thermo 1000
thermo_style custom step temp pe ke etotal press density
thermo_modify flush yes
{thermostat_fix}
run {equilibration_steps}
unfix thermostat
reset_timestep 0
fix integrator all nve
compute gr all rdf {MD_RDF_BINS} 1 1
{rdf_fix}
dump snapshots all custom {rdf_block_steps} trajectory.lammpstrj id x y z
dump_modify snapshots sort id
run {production_steps}
"""
(workdir / "in.al_md").write_text(input_text, encoding="utf-8")
environment = os.environ.copy()
environment["OMP_NUM_THREADS"] = "1"
started = time.perf_counter()
rdf_path = workdir / "rdf_blocks.dat"
log_path = workdir / "log.lammps"
trajectory_path = workdir / "trajectory.lammpstrj"
# Fresh electronic states imply fresh pair tables. An old completed log
# does not certify that its trajectory used these same potentials.
with (workdir / "screen.log").open("w", encoding="utf-8") as screen:
subprocess.run(
[launcher, "-np", str(MPI_PROCESSES_PER_MD_CASE), lammps,
"-in", "in.al_md", "-log", "log.lammps"],
cwd=workdir, env=environment, stdout=screen,
stderr=subprocess.STDOUT, check=True,
)
radius, g_blocks = _read_lammps_rdf(rdf_path)
positions, box_length_bohr = _read_lammps_trajectory(trajectory_path)
k, sii, sii_sem, vectors_per_bin = _direct_structure_factor(
positions,
box_length_bohr,
min(MD_K_MAX_BOHR_INV, float(payload["k_bohr_inv"][-1])),
)
drift, mean_temperature, version = _read_lammps_nve_audit(
log_path
)
return {
"md_r_bohr": radius,
"md_gii_r": np.mean(g_blocks, axis=0),
"md_gii_block_sem": np.std(g_blocks, axis=0, ddof=1)
/ np.sqrt(g_blocks.shape[0]),
"md_k_bohr_inv": k,
"md_sii_k": sii,
"md_sii_block_sem": sii_sem,
"md_sii_vectors_per_bin": vectors_per_bin,
"md_box_length_bohr": np.asarray(box_length_bohr),
"md_atoms": np.asarray(4 * MD_CELLS_PER_AXIS**3),
"md_rdf_blocks": np.asarray(g_blocks.shape[0]),
"md_timestep_omega_p_inv": np.asarray(dt_omega),
"md_timestep_ps": np.asarray(timestep_ps),
"md_equilibration_steps": np.asarray(equilibration_steps),
"md_production_steps": np.asarray(production_steps),
"md_equilibration_omega_p_inv": np.asarray(
MD_EQUILIBRATION_OMEGA_P_INV
),
"md_production_omega_p_inv": np.asarray(MD_PRODUCTION_OMEGA_P_INV),
"md_ensemble_sequence": np.asarray("NVT->NVE"),
"md_structure_factor_estimator": np.asarray(
"complete periodic reciprocal-shell and trajectory-frame average"
),
"md_sii_uncertainty_definition": np.asarray(
"SEM across shell-averaged saved production frames"
),
"md_trajectory_frames": np.asarray(positions.shape[0]),
"md_nve_relative_energy_drift": np.asarray(drift),
"md_nve_mean_temperature_k": np.asarray(mean_temperature),
"md_lammps_version": np.asarray(version),
"md_reused_existing_run": np.asarray(False),
"md_elapsed_s": np.asarray(time.perf_counter() - started),
}
def add_same_potential_md(states: dict[str, dict[str, np.ndarray]]) -> None:
"""Add independent MD results with bounded MPI concurrency."""
with ProcessPoolExecutor(max_workers=MAX_PARALLEL_MD_CASES) as pool:
futures = {
pool.submit(run_same_potential_md, payload): identifier
for identifier, payload in states.items()
}
for future in as_completed(futures):
identifier = futures[future]
states[identifier].update(future.result())
print(f"[computed MD] {identifier}")
def _refresh_metadata(payload: dict[str, np.ndarray]) -> None:
"""Record MD diagnostics and the final portable field inventory."""
metadata = json.loads(str(payload["metadata_json"].item()))
md_enabled = "md_sii_k" in payload
metadata["configuration"]["same_potential_md"] = {
"enabled": md_enabled,
"atoms": 4 * MD_CELLS_PER_AXIS**3,
"ensemble_sequence": "NVT->NVE",
"timestep_omega_p_inv": MD_TIMESTEP_OMEGA_P_INV,
"equilibration_omega_p_inv": MD_EQUILIBRATION_OMEGA_P_INV,
"production_omega_p_inv": MD_PRODUCTION_OMEGA_P_INV,
"rdf_bins": MD_RDF_BINS,
"trajectory_frames": (
int(payload["md_trajectory_frames"]) if md_enabled else None
),
"sii_estimator": "complete periodic reciprocal-shell average",
"reciprocal_vectors_per_bin": "all available half-space modes",
"uncertainty": "SEM across shell-averaged saved production frames",
}
if md_enabled:
metadata["convergence"]["md_nve_relative_energy_drift"] = float(
payload["md_nve_relative_energy_drift"]
)
metadata["fields"] = sorted(key for key in payload if key != "metadata_json")
payload["metadata_json"] = np.asarray(
json.dumps(metadata, sort_keys=True, separators=(",", ":"))
)
def save_candidates(states: dict[str, dict[str, np.ndarray]]) -> None:
"""Write the complete unreviewed candidate package and its checksums."""
CANDIDATE_DIR.mkdir(parents=True, exist_ok=True)
records: list[dict[str, Any]] = []
for identifier, payload in sorted(states.items()):
for key in (
"r_bohr",
"gii_r",
"vmhnc_r_bohr",
"vmhnc_gii_r",
"vmhnc_k_bohr_inv",
"vii_r_ha",
"ion_density_bohr3",
"md_r_bohr",
"md_gii_r",
"md_gii_block_sem",
):
payload.pop(key, None)
_refresh_metadata(payload)
path = CANDIDATE_DIR / f"{identifier}.npz"
np.savez_compressed(path, **payload)
records.append(
{
"state_id": identifier,
"status": "candidate_unreviewed",
"baseline_file": path.name,
"baseline_sha256": sha256_file(path),
"zbar_partition": float(payload["zbar_partition"]),
"hnc_output_residual": float(payload["hnc_output_residual"]),
"vmhnc_output_residual": float(
payload["vmhnc_hnc_output_residual"]
),
"vmhnc_eta": float(payload["vmhnc_eta"]),
"vmhnc_variational_residual": float(
payload["vmhnc_variational_residual"]
),
"same_potential_md": "md_sii_k" in payload,
**(
{
"md_nve_relative_energy_drift": float(
payload["md_nve_relative_energy_drift"]
)
}
if "md_nve_relative_energy_drift" in payload
else {}
),
}
)
print(f"[candidate] {path}")
manifest = {
"schema_version": "otter_candidate_manifest_v1",
"benchmark_id": BENCHMARK_ID,
"producer": {
"project": "Otter",
"project_version": otter_version,
"script_relative_path": str(SCRIPT_PATH.relative_to(ROOT)),
"script_sha256": sha256_file(SCRIPT_PATH),
},
"configuration": {
"structure_model": "IS",
"xc_models": [str(item["xc_model"]) for item in XC_MODELS],
"ionic_closures": ["HNC", "Rosenfeld--Ashcroft VMHNC"],
"electronic_state_reused_between_closures": True,
"same_potential_md": {
"enabled": bool(RUN_SAME_POTENTIAL_MD),
"atoms": 4 * MD_CELLS_PER_AXIS**3,
"ensemble_sequence": "NVT->NVE",
"timestep_omega_p_inv": MD_TIMESTEP_OMEGA_P_INV,
"equilibration_omega_p_inv": MD_EQUILIBRATION_OMEGA_P_INV,
"production_omega_p_inv": MD_PRODUCTION_OMEGA_P_INV,
"trajectory_blocks": 20,
"sii_estimator": "complete periodic reciprocal-shell average",
"radial_bin_width_angstrom_inv": (
MD_K_BIN_WIDTH_ANGSTROM_INV
),
"reciprocal_vectors_per_bin": "all available half-space modes",
"uncertainty": (
"SEM across shell-averaged saved production frames"
),
},
},
"states": records,
}
(CANDIDATE_DIR / "candidate_manifest.json").write_text(
json.dumps(manifest, indent=2) + "\n", encoding="utf-8"
)
def solve_case(
state: dict[str, Any], xc: dict[str, str]
) -> tuple[str, dict[str, np.ndarray]]:
"""Calculate one IS state, then solve both closures on that state."""
started = time.perf_counter()
hnc_workflow = solve_plasma_workflow(
workflow_config(state, xc, bridge_model="none")
)
hnc_elapsed_s = time.perf_counter() - started
electronic = dict(hnc_workflow["electronic"])
started = time.perf_counter()
vmhnc_workflow = continue_plasma_workflow_from_electronic_result(
workflow_config(state, xc, bridge_model="rosenfeld_ashcroft"),
electronic_kind=str(electronic["kind"]),
electronic_result=dict(electronic["result"]),
)
payload = pack_result(
hnc_workflow,
vmhnc_workflow,
state,
xc,
hnc_elapsed_s,
time.perf_counter() - started,
)
return case_id(state, xc), payload
def solve_all_states() -> dict[str, dict[str, np.ndarray]]:
"""Calculate all state/XC closures and same-potential MD cases."""
solved: dict[str, dict[str, np.ndarray]] = {}
failures: dict[str, str] = {}
cases = [(state, xc) for state in STATES for xc in XC_MODELS]
workers = max(1, min(int(MAX_CASE_WORKERS), len(cases)))
with ProcessPoolExecutor(max_workers=workers) as pool:
futures = {
pool.submit(solve_case, state, xc): (state, xc)
for state, xc in cases
}
for future in as_completed(futures):
state, xc = futures[future]
try:
identifier, payload = future.result()
except Exception as exc:
failures[case_id(state, xc)] = f"{type(exc).__name__}: {exc}"
continue
solved[identifier] = payload
print(f"[computed closures] {identifier}")
if RUN_SAME_POTENTIAL_MD and not failures:
add_same_potential_md(solved)
# Preserve successful closures even if a different state/XC failed.
save_candidates(solved)
(CANDIDATE_DIR / "failures.json").write_text(json.dumps(failures, indent=2))
if failures:
raise RuntimeError(f"Schörner state/XC failures: {failures}")
return solved
def inverse_bohr_sii(
state: dict[str, np.ndarray],
k_key: str = "k_bohr_inv",
sii_key: str = "sii_k",
) -> tuple[np.ndarray, np.ndarray]:
"""Return one Otter curve with wavenumber in inverse ångström."""
k_angstrom_inv = (
np.asarray(state[k_key], dtype=float) / BOHR_TO_ANGSTROM
)
return k_angstrom_inv, np.asarray(state[sii_key], dtype=float)
def main() -> None:
reference_curves = load_reference_curves()
if not USE_PRECOMPUTED_DATA:
otter_states = solve_all_states()
elif USE_RECOMPUTED_CANDIDATES:
otter_states = load_recomputed_candidates()
else:
otter_states = load_precomputed_states()
if any(bool(payload.get("md_is_historical", False)) for payload in otter_states.values()):
print("MD rows below are historical old-potential runs; HNC and VMHNC use refreshed Otter data.")
print(
f"{'case':>29s} {'method':>8s} {'RMSE':>12s} "
f"{'MAE':>12s} {'max|delta|':>12s}"
)
for state in STATES:
reference_id = str(state["state_id"])
k_ref, sii_ref = reference_curves[reference_id]
for xc in XC_MODELS:
identifier = case_id(state, xc)
payload = otter_states[identifier]
methods = (
("HNC", "k_bohr_inv", "sii_k"),
("VMHNC", "k_bohr_inv", "vmhnc_sii_k"),
("MD", "md_k_bohr_inv", "md_sii_k"),
)
for method, k_key, sii_key in methods:
if k_key not in payload or sii_key not in payload:
continue
k_otter, sii_otter = inverse_bohr_sii(payload, k_key, sii_key)
mask = (k_ref >= k_otter[0]) & (k_ref <= k_otter[-1])
delta = np.interp(k_ref[mask], k_otter, sii_otter) - sii_ref[mask]
print(
f"{identifier:>29s} {method:>8s} "
f"{np.sqrt(np.mean(delta**2)):12.4e} "
f"{np.mean(np.abs(delta)):12.4e} "
f"{np.max(np.abs(delta)):12.4e}"
)
if "md_k_bohr_inv" in payload and "md_sii_k" in payload:
k_md, sii_md = inverse_bohr_sii(payload, "md_k_bohr_inv", "md_sii_k")
for method, k_key, sii_key in methods[:2]:
k_closure, sii_closure = inverse_bohr_sii(payload, k_key, sii_key)
mask = (k_md >= k_closure[0]) & (k_md <= k_closure[-1])
delta = np.interp(k_md[mask], k_closure, sii_closure) - sii_md[mask]
print(
f"{identifier:>29s} {method + '-MD':>8s} "
f"{np.sqrt(np.mean(delta**2)):12.4e}"
)
# %%
# Static ion structure factors
# ----------------------------
#
# Each Otter curve has a distinct color and dash pattern from the project-wide
# ``bing`` palette. Markers are the corrected digitized values; the raw CSV is
# never rewritten.
set_style("thesis", palette="bing")
fig, axes = plt.subplots(1, 2, figsize=grid_figsize(1, 2))
colors = PALETTES["bing"]
reference_style = MODEL_STYLES["reference"]
curve_styles = {
("lda", "HNC"): (colors[0], "-", 2.2),
("lda", "VMHNC"): (colors[1], "--", 2.0),
("lda", "MD"): (colors[4], "-.", 1.8),
("pbe", "HNC"): (colors[2], ":", 2.2),
("pbe", "VMHNC"): (colors[3], (0, (6, 2)), 2.0),
("pbe", "MD"): (colors[5], (0, (3, 1, 1, 1)), 1.8),
}
method_fields = (
("HNC", "k_bohr_inv", "sii_k"),
("VMHNC", "k_bohr_inv", "vmhnc_sii_k"),
("MD", "md_k_bohr_inv", "md_sii_k"),
)
for axis, state in zip(axes, STATES, strict=True):
reference_id = str(state["state_id"])
k_ref, sii_ref = reference_curves[reference_id]
for xc in XC_MODELS:
payload = otter_states[case_id(state, xc)]
for method, k_key, sii_key in method_fields:
if k_key not in payload or sii_key not in payload:
continue
color, linestyle, linewidth = curve_styles[(xc["key"], method)]
k_otter, sii_otter = inverse_bohr_sii(payload, k_key, sii_key)
axis.plot(
k_otter,
sii_otter,
color=color,
linestyle="--" if method == "MD" else linestyle,
marker="o" if method == "MD" else None,
markersize=2.5,
markevery=3,
linewidth=linewidth,
alpha=0.72 if method != "MD" else 0.60,
label=(
f"{xc['label']} {method}"
+ (" (old potential)" if bool(payload.get("md_is_historical", False)) else "")
+ " ($\\pm 2$ SEM)"
if method == "MD"
else f"{xc['label']} {method}"
),
)
if method == "MD":
sem = np.asarray(payload["md_sii_block_sem"], dtype=float)
axis.fill_between(
k_otter,
sii_otter - 2.0 * sem,
sii_otter + 2.0 * sem,
color=color,
alpha=0.14,
linewidth=0.0,
)
axis.scatter(
k_ref,
sii_ref,
s=42,
marker=reference_style["marker"],
linewidths=1.2,
facecolors=reference_style["markerfacecolor"],
edgecolors=reference_style["color"],
label="Schörner et al. (2022), DFT-MD",
zorder=3,
)
axis.axhline(1.0, color="0.55", ls=":", lw=0.8)
axis.set(
xlim=(0.0, 8.3),
ylim=(0.0, 2.25 if float(state["te_ev"]) == 1.0 else 1.55),
xlabel=r"$k\ (\mathrm{\AA}^{-1})$",
ylabel=r"$S_{ii}(k)$",
title=(
rf"Al: $T_e=T_i={state['te_ev']:g}$ eV, "
rf"$\rho={state['rho_g_cc']:g}$ g cc$^{{-1}}$"
),
)
legend_handles, legend_labels = axes[0].get_legend_handles_labels()
fig.legend(
legend_handles,
legend_labels,
fontsize=7.2,
ncol=4,
loc="upper center",
bbox_to_anchor=(0.5, 0.99),
)
fig.tight_layout(rect=(0.0, 0.0, 1.0, 0.90))
saved_paths = save_figure(
fig,
FIGURE_DIR / "schorner_et_al_2022_al_sii",
formats=("png", "pdf"),
)
print(
"Saved figures: "
+ ", ".join(str(path.relative_to(ROOT)) for path in saved_paths.values())
)
plt.show()
if __name__ == "__main__":
main()